Connecting powerful LLM APIs to your products is exciting, but ensuring they run reliably is another story. Discover essential design principles to prevent service interruptions when these external AI tools hit snags.
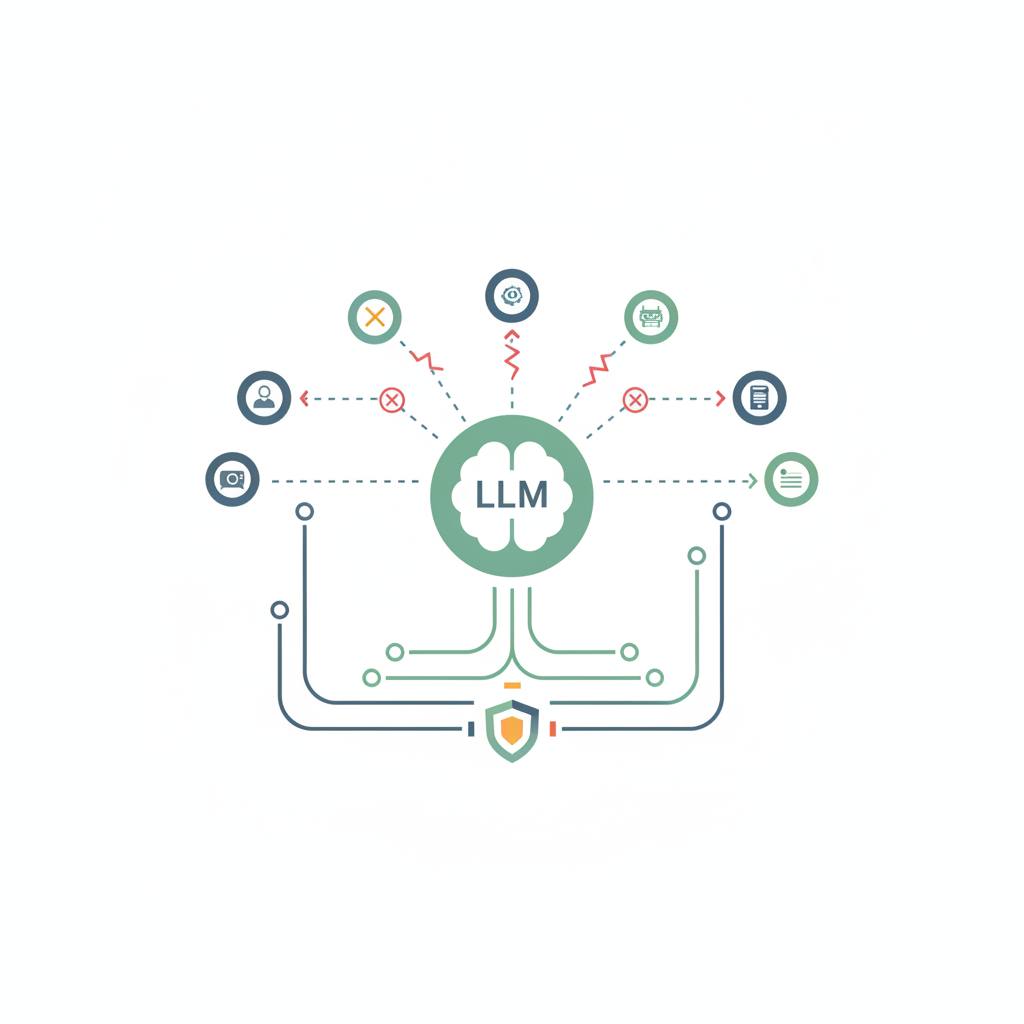
Welcome to WondTech! Today, we're diving into a crucial topic for any developer using AI: how to keep your services running smoothly even when Large Language Model (LLM) APIs encounter issues. Connecting these powerful models to your products is exciting, but ensuring they operate reliably without interruption when external APIs fail is the real challenge. In real-world operations, external AI APIs can face response delays, network errors, rate limits, temporary server outages, or even processing failures due to long inputs. Handling these problems with simple 'try/catch' blocks can make a minor API hiccup look like a full service outage. That’s why we need to plan for failure from the start, building a system that can gracefully handle these inevitable setbacks.
First, don't wait forever. It's essential to set a timeout for any request you send to an external API. AI models can take varying amounts of time to respond based on request complexity and server status. Without a timeout, a user request might hang indefinitely, occupying server connections and delaying other tasks. This timeout should be flexible; for instance, real-time UI interactions demand a short timeout, whereas background document analysis can allow for a longer wait.
Second, don't retry blindly. When a request fails, it's not always wise to simply send it again and again without thought. The error might be due to a wrong API key or an invalid request format, which will never succeed no matter how many times you try. Instead, categorize errors into two types: transient (like network errors, 429 Rate Limit, or some 5xx server errors) and permanent (such as authentication failures, incorrect request data). Your retry policy should depend on the error type.
Third, employ 'Exponential Backoff' for retries. If a request fails and you decide to retry, don't do it immediately. This can overwhelm the server, especially if many clients are retrying simultaneously. Instead, wait for progressively longer periods between each attempt (e.g., one second after the first failure, then two seconds, then four seconds). Also, consider adding a small random delay, known as 'jitter', to prevent all requests from hitting the server at the exact same moment.
Finally, consider fallbacks. Your entire service shouldn't grind to a halt just because the primary AI model is unavailable. Depending on the task's nature, you can switch to a secondary model or offer a simpler, alternative functionality. Planning for these scenarios ensures your applications remain resilient and reliable, even when things don't go perfectly with external AI APIs. These fundamental principles are key to building robust and stable services in an increasingly AI-dependent world.