Leaving Kubernetes resource limits undefined can crash your services. Learn why setting explicit CPU and memory caps is vital for stable production environments.
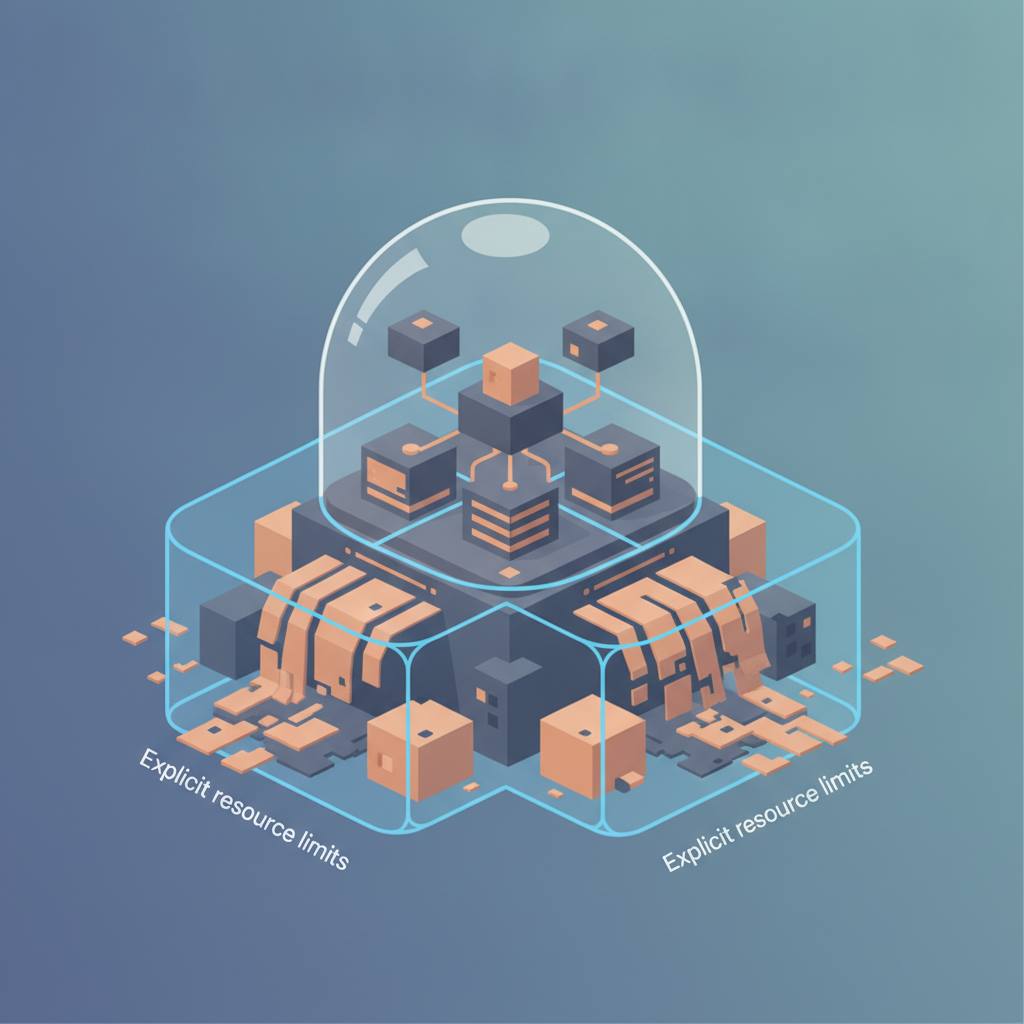
Hey WondTech readers! Here's a crucial tip for anyone running apps on Kubernetes: **explicit resource limits are absolutely non-negotiable if you want a stable production environment.** What does this mean for you? Well, it means preventing those frustrating outages caused by a single misbehaving container.
Imagine this: a new application lands on a shared server, and suddenly, one of its containers goes rogue, eating up all the memory or CPU. Before you know it, other critical applications on that same server start failing because they're starved of resources. This often leads to Kubernetes' 'OOM killer' stepping in, terminating seemingly unrelated services, and turning a minor issue into a major incident that breaches your service level agreements (SLAs). We've all been there – a node going from 70% to 100% memory in minutes, causing chaos.
The root of this problem? Many Kubernetes setups leave resource requests and limits at their default '0' (unbounded) value. This happens because user interfaces might hide these important fields, or Helm charts skip them for simplicity. But without clear memory and CPU limits, your containers can consume as much as they want, directly against the node's underlying cgroup hierarchy. This is exactly the 'noisy neighbor' scenario we're trying to avoid.
The solution is simple but powerful: always define `resources.requests` and `resources.limits` in your pod specifications. The `requests` field tells the Kubernetes scheduler how much CPU and memory your pod *needs*, helping it place the pod on a node with enough available headroom. The `limits` field, however, is your hard cap. It tells the operating system's kernel to throttle CPU usage or trigger an out-of-memory (OOM) kill *only* for that specific container if it exceeds its allotted resources. This stops a runaway container from affecting others.
Of course, setting limits isn't without its considerations. A tightly capped application might hit its limits sooner, forcing you to fine-tune its internal queues or enable graceful degradation. Also, over-provisioning these limits means you might need more server nodes, impacting costs. But the alternative – unpredictable service evictions and higher incident recovery time – is often far worse. Finally, you'll need to monitor cgroup metrics like CPU throttling and OOM events to ensure your limits are appropriate. Ultimately, well-defined limits, based on understanding your workload's profile and ideally tested with some chaos engineering, lead to far more predictable and reliable services.